Story
LiveA picture book that stars your people, read aloud in your own voice.
Today: One line in, a 6-page narrated picture book out.
Its own app
Decosa Studio
Stories, songs, films and voices from one project. Add your cast once (a few photos, twenty seconds of your voice) and every pack uses them.
Private by default. Faces and voices come in only with consent you record yourself, and are never used for training.
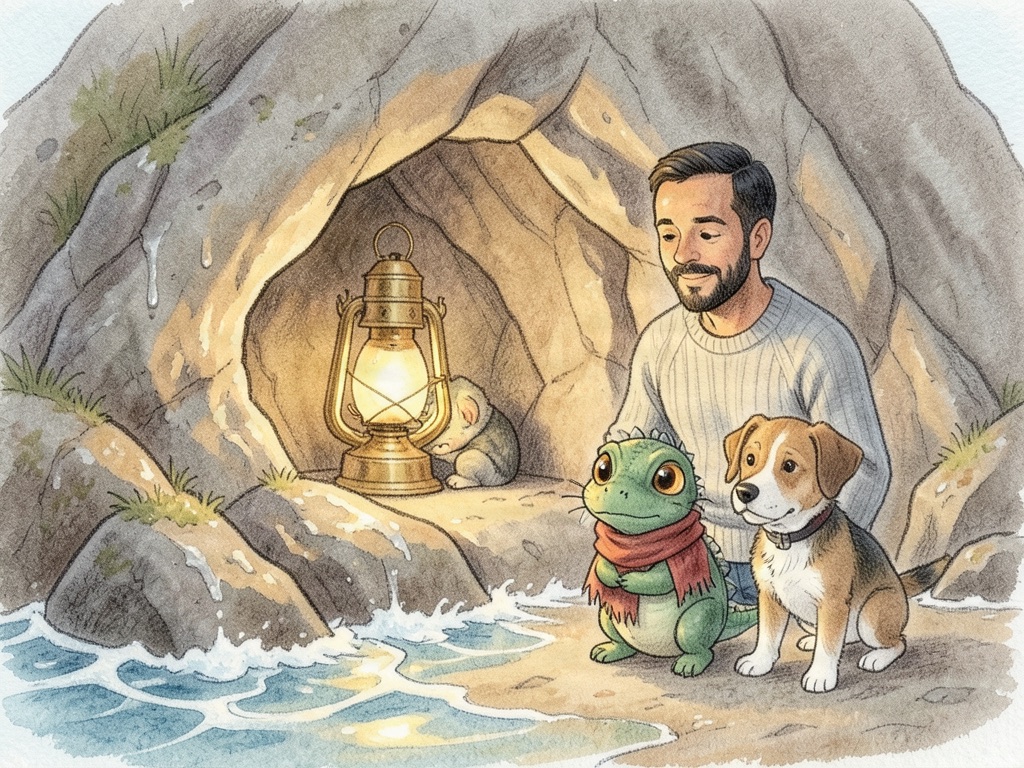
Sam placed the lantern in the mouth of the cave, and the dark doorway turned warm and glowing.
What do you do?Creators (Studio)
Before it goes out, whatever you made it with.
A project holds your cast (faces and voices, each with the consent it came in with), your world and your look. You add them once. Story, Film, Characters & Worlds and Brand & Ads all use the project today; Music and Voice will read the same cast next.
Looking for projects on this device…
Each pack is a set of tools that share your project.
A picture book that stars your people, read aloud in your own voice.
Today: One line in, a 6-page narrated picture book out.
Its own app
A song about someone, or a music video for your own track.
Today: Cleared songs, music videos for your own track, and the songs in your mix.
4 tools
Turn an idea, a script or your story into a short film with your cast.
Today: An idea, a script or your story becomes a short film with your cast.
3 tools
Your words performed: in your own voice, or by a consented cast.
Today: Dubbing in your own voice, and audio dramas.
2 tools
Design a character and their world, then use them everywhere.
Today: Describe someone: a sheet, four sketches, a voice, and a chat.
1 tool
Short video ads with your real product, labelled as AI.
Today: Your product photos and claims in; a labelled video ad out.
3 tools
Before you publish, whatever you made it with.
Check any file's C2PA credential and render receipt.
PreviewFind samples, re-played melodies and lifted lyrics before release.
LiveSplits add up and every ISRC, ISWC and IPI is valid.
LiveIs this video directed to children? Checked factor by factor before it goes out.
LiveWhat to declare when you upload an AI-assisted single.
ComingOne project, many packs. Your project keeps the cast (photos, a voice, traits), the world (places, objects, what happened last time) and the look. Packs read it, so you never re-upload a face or a voice.
Three speeds. Sketch (seconds: text, pictures, narration), preview (fast video) and final (full-quality video). Everything shows as a sketch first and upgrades in place.
Proof in every file. Each picture, track and clip carries a C2PA content credential and a signed render receipt naming the model, its licence and the settings.
Hosted or yours. Studio runs on Decosa's GPUs, or on your own 96 GB card (self-host). Two older video tools (the Studio video queue and the disclosed UGC ad) render on fal, a partner GPU provider, under our account; no photo, voice or consent recording from your project goes there. That queue pauses when the provider account or the daily cap runs out, and the console says whether it is open right now.
Hosted packs use only permissively licensed or checked models. MiniMax H3 is used under Decosa's licence from MiniMax.
Every tool has its own API with dk_ keys; each tool's page lists its routes. Story is POST /studio/projects, then /studio/projects/{id}/cast and /studio/projects/{id}/stories, streaming each page as it's ready.
Paste one of these into Claude Code, Codex or another coding agent. The first wires your project to the hosted API with your DECOSA_API_KEY. The second pulls our containers and runs the same stack on your own GPU, with no Decosa charges.
Authorization: Bearer $DECOSA_API_KEY (or a demo session token)# Decosa Studio: use the hosted API
You are wiring Decosa Studio into this project. It renders songs (MiniMax-Music3, or ACE-Step 1.5 as a
fast option), images (Qwen-Image-2512) and short video clips. Music and images run on open models on Decosa's hosted service; hosted
video runs on MiniMax H3 Max through fal at fal's list price. Use only the endpoints below. If you need something
else, stop and ask me.
- Base URL: `https://api.decosa.ai`
- Health check: `GET https://api.decosa.ai/healthz` returns `{"ok": true, "asr": bool, "llm": bool, "live_sessions": n, "queue": n}`.
## Auth: API key (or a demo session)
1. Preferred: an API key. Create one on the tool page with "Get an API key"; it looks like `dk_…` and is shown
only once. Keep it in an environment variable, never in code: `DECOSA_API_KEY=dk_…`. Send
`Authorization: Bearer $DECOSA_API_KEY` on calls that need auth; WebSockets take `?token=$DECOSA_API_KEY` in the URL.
2. Without a key, use a short demo session: `POST https://api.decosa.ai/demo/session` with JSON `{"vertical": "studio"}` returns
`{"token": "<opaque>", "expires_at": <unix seconds>, "budget": {"seconds_audio": 300, "llm_tokens": 20000}}`.
3. Send `Authorization: Bearer <token>` on calls that need it (session-bound calls such as live audio, replay, chat and
render jobs). WebSockets take `?token=<token>` in the URL instead. These need no token: `GET /healthz`,
`GET /demo/scripts`, `GET /demo/recordings`, `GET /demo/recordings/{id}/events`, `GET /studio/gallery`,
`GET /studio/jobs/{id}`, `GET /receipts/{id}`.
4. Demo-session limits: a limited number of sessions per network per hour (the current limits are in `demo_sessions` of GET /healthz), and a global cap on concurrent live audio sessions. Over a limit the API answers
HTTP 429 with a `Retry-After` header (seconds): wait that long, then retry. Reuse a token until `expires_at`.
5. The API keeps no PII; session transcripts live in memory and are deleted when the session ends.
## Gallery
`GET https://api.decosa.ai/studio/gallery` returns
`[{"id", "kind": "music"|"image"|"video", "title", "prompt", "model", "url", "seed", "duration_s"?}]`.
Media files are served under `/studio/media/...`; resolve relative `url` values against the base URL.
## Render jobs
- `POST https://api.decosa.ai/studio/jobs` with `{"kind": "music"|"image"|"video", "prompt": "...", "params": {}}` returns
`{"job_id", "status": "queued", "position": N}`. Optional `params`: `seed`; for music `lyrics`, `seconds` and
`engine: "acestep"`; for images `aspect` (`square`, `landscape`, `portrait`).
- `GET https://api.decosa.ai/studio/jobs/{id}` (no token) returns `{"status": "queued"|"running"|"done"|"failed", "url"?,
"receipt_url"?, "credential"?, "notice"?, "model"?, "error"?, "paused"?, "note"?}`. Poll every few seconds until
`done` or `failed`. `paused: true` means a live demo session is using the GPU; the job continues afterwards. Typical
times on our box: music about 1 minute, an image about 2 minutes.
- Each token or key can queue at most 3 jobs. Prompts that imitate a named artist, copy a song or clone a voice are
refused with 422 `{error, category, policy_url}`. Voice jobs are not offered.
- Video needs an API key (`dk_…`): 403 `key_required` for a demo token, about $0.40 per 5 s 1080P clip at fal's list
price with no markup, 2 per key per day, and a daily cap for the whole service (402 `daily_cap`). `GET
https://api.decosa.ai/studio/pricing` says whether video can run right now (`video_available`); while the fal account is out
of credit, video answers 402 `provider_out_of_credit` and nothing is charged.
- Errors may not be JSON (for example a 502 from the proxy while the service restarts). Check the status code before
parsing, and on 429 or 5xx wait and retry. A job interrupted by a restart comes back as `failed` with a reason.
- For MiniMax-Music3 results, show the `notice` ("Powered by MiniMax-Music3") next to the player: the licence requires it.
Every finished render carries a C2PA content credential and a signed render receipt (`receipt_url`: model, weights
digest, seed, prompt hash, output hash). Nobody re-renders it to check the work: the receipt is our signed statement,
weaker than the text receipts that a gateway countersigns.
## Example: TypeScript
```ts
const BASE = "https://api.decosa.ai";
// Prefer your API key (dk_…); fall back to a short demo session.
async function call(path: string, init: RequestInit = {}): Promise<any> {
for (let attempt = 0; ; attempt++) {
const r = await fetch(`${BASE}${path}`, init);
const body = (r.headers.get("content-type") ?? "").includes("application/json") ? await r.json() : { error: await r.text() };
if (r.ok) return body;
if ((r.status === 429 || r.status >= 500) && attempt < 5) {
await new Promise((ok) => setTimeout(ok, 1000 * Number(r.headers.get("Retry-After") ?? 10)));
continue;
}
throw new Error(`${r.status}: ${body.error ?? body.detail ?? "request failed"}`);
}
}
const token: string =
process.env.DECOSA_API_KEY ??
(await call("/demo/session", { method: "POST", headers: { "Content-Type": "application/json" }, body: JSON.stringify({ vertical: "studio" }) })).token;
const auth = { Authorization: `Bearer ${token}` };
const job = await call("/studio/jobs", {
method: "POST",
headers: { ...auth, "Content-Type": "application/json" },
body: JSON.stringify({ kind: "music", prompt: "Warm, minimal piano, 92 BPM, no vocals", params: {} }),
});
console.log("queued at position", job.position);
while (true) {
await new Promise((r) => setTimeout(r, 3000));
const s = await call(`/studio/jobs/${job.job_id}`);
if (s.status === "done") { console.log("render:", new URL(s.url, BASE).href, s.notice ?? "", "receipt:", s.receipt_url); break; }
if (s.status === "failed") throw new Error(`render failed: ${s.error ?? "no reason given"}`);
}
```
## Example: Python (`pip install requests`)
```python
import os
import time, requests
from urllib.parse import urljoin
BASE = "https://api.decosa.ai"
def call(method, path, **kw):
"""Return the JSON body, retrying 429/5xx; errors can be plain text (e.g. a 502 while the service restarts)."""
for attempt in range(6):
r = requests.request(method, f"{BASE}{path}", timeout=60, **kw)
is_json = r.headers.get("content-type", "").startswith("application/json")
if r.ok:
return r.json()
if r.status_code in (429, 500, 502, 503, 504) and attempt < 5:
time.sleep(int(r.headers.get("Retry-After", "10")))
continue
detail = r.json() if is_json else {"error": r.text[:200]}
raise SystemExit(f"{method} {path}: HTTP {r.status_code}: {detail.get('error') or detail.get('detail')}")
token = os.environ.get("DECOSA_API_KEY") or call("POST", "/demo/session", json={"vertical": "studio"})["token"] # dk_… API key preferred
auth = {"Authorization": f"Bearer {token}"}
job = call("POST", "/studio/jobs", headers=auth, json={"kind": "image", "prompt": "Documentary photo of a harbor at dusk", "params": {}})
print("queued at position", job["position"])
while True:
time.sleep(3)
s = call("GET", f"/studio/jobs/{job['job_id']}")
if s["status"] == "done":
print("render:", urljoin(BASE, s["url"]), "receipt:", urljoin(BASE, s.get("receipt_url", "")))
break
if s["status"] == "failed":
raise SystemExit(f"render failed: {s.get('error', 'no reason given')}")
```
## What to build
1. A gallery view from `/studio/gallery`.
2. A request form that queues a job, shows its queue position and status, and shows the result.
Voice cloning is not part of the public API. It needs a signed consent record from the voice owner.
On request. The container images and the compose file aren’t public yet. Ask for self-host access and Decosa sends the registry (DECOSA_REGISTRY) and the compose file’s URL (DECOSA_COMPOSE_URL) these steps use. They are the steps we tested end to end on a fresh machine.
# Decosa Studio: run it yourself (containers)

You are setting up Decosa Studio to run entirely on this machine's NVIDIA GPU(s). Nothing is sent to Decosa's
hosted API and there are no Decosa charges. The local service speaks the same API as the hosted one, so apps built
against the hosted API only need a new base URL.

Status: the container images (${DECOSA_REGISTRY}/decosa-*) and the compose file are on request while self-host is in early access (not on a public registry yet): ask at https://decosa.ai/contact?topic=self-host, and Decosa sends the registry as DECOSA_REGISTRY, the compose file URL as DECOSA_COMPOSE_URL, and pull access. If a pull fails with
"not found", "denied" or "unauthorized", stop and tell me. Do not substitute other images.

Hardware: 1x RTX PRO 6000 (96 GB). Two RTX 5090s are not enough for the studio models. Linux x86_64 with a recent NVIDIA driver.

Ask me before any command that needs sudo, and show me the command first.

## Step 0: set up with a coding agent, rehearse on mock data, then go private

This prompt is for a coding agent running on the machine that will host the service. We recommend Claude Code with
Claude Opus 5.5; any capable coding agent works. Work in this order:

1. Set up on mock data only. During the whole setup you (the agent) work with the synthetic sample bundle below and
   nothing else. Do not ask me for real data, and do not open, read, list or copy files that hold real data, even to
   "test with something realistic".
2. Rehearse. When the steps below are done and the service is healthy, fetch the mock-data bundle for this tool,
   https://decosa.ai/samples/studio.zip (942 KB, 11 checks, synthetic or openly licensed: see `licence` in expected.json),
   show me what is in it, and run the rehearsal against the local API:
   `docker compose exec api python scripts/rehearse.py studio` (the api image carries the same bundle under /app/rehearsal/studio/;
   with no key set, the script asks the local API for a short demo token). From a decosa-api checkout instead:
   `python scripts/rehearse.py studio --bundle studio.zip --base-url http://127.0.0.1:<PORT>`.
   It sends the mock inputs to the local API and prints PASS or FAIL for each expected property (for example: "the gallery lists music, images and video", "the gallery has at least one video", "every MiniMax-Music3 track carries its licence notice"). Show me
   the full output. Every check must pass. If one fails, fix the install and run it again; never edit `expected.json`
   to make a check pass.
3. Stop there. Once the rehearsal passes, tell me, and I will run my own data against the local API myself, on this
   machine.

For the person running this: a coding agent that runs in the cloud sees everything in its context, including files it
reads, command output and anything pasted into the chat. Keep real data out of the chat and out of anything the agent
can read. Switch to your own data only after the rehearsal has passed and the agent's work is done.

## Steps
1. Check the GPU and driver: `nvidia-smi`. If it fails, stop and tell me; do not install drivers without asking.
   Check free disk: the first start downloads model weights (tens of GB).
2. Docker: if `docker compose version` fails, install Docker Engine and the compose plugin using Docker's official
   instructions for this distribution (docs.docker.com/engine/install). Add me to the `docker` group only if I agree.
3. NVIDIA Container Toolkit: if `docker run --rm --gpus all ubuntu nvidia-smi` fails, install the toolkit using
   NVIDIA's official instructions (docs.nvidia.com/datacenter/cloud-native/container-toolkit/latest/install-guide.html),
   then run `sudo nvidia-ctk runtime configure --runtime=docker` and `sudo systemctl restart docker`. Re-run the check.
4. Fetch the compose file:
   `mkdir -p ~/decosa && cd ~/decosa && curl -fsSL "${DECOSA_COMPOSE_URL}" -o compose.yaml`
   Read it. If it references an `.env` file or variables, ask me for any values. Never print secrets.
5. Pull and start: `docker compose pull && docker compose up -d`.
6. Wait for health. Find the host port that compose.yaml publishes for the API (`docker compose ps`), then poll
   `curl -fsS http://localhost:<PORT>/healthz` every 10 s until it answers (`asr` and `llm` may be false: the studio
   uses neither, except the optional model check on prompts). The first start can take a while as weights download. Show me `docker compose logs --tail=50` if it
   has not come up after 20 minutes.
7. Smoke test: `curl -fsS -X POST http://localhost:<PORT>/demo/session -H 'Content-Type: application/json' -d '{"vertical":"studio"}'`
   should return a token. Queue one short music job with it (`POST /studio/jobs`, see the hosted prompt) and poll
   `GET /studio/jobs/{id}` until `done`; about 40 s for MiniMax-Music3 once the model is loaded.
8. Report back: GPU model(s) and memory, Docker and toolkit versions, the `/healthz` output, and the local base URL.

No NVIDIA GPU? Parts of this tool also run on an Apple Silicon Mac (MLX, 64 GB of unified memory or more): use https://decosa.ai/prompts/studio-mac.md instead.
Same app, same pinned models, your hardware. Nothing goes to our servers and there are no Decosa charges.
MiniMax-Music3 needs a GPU.
Needs about 50 GB of GPU memory at the smallest settings; 24 GB available.
Needs about 50 GB of GPU memory at the smallest settings; 32 GB available.
MiniMax-Music3 needs about 50 GB on one GPU; each GPU here has 32 GB.
Needs about 50 GB of GPU memory at the smallest settings; 48 GB available.
The standard tier fits (106.2 of 80 GB).
The standard tier fits (106.2 of 96 GB). The best tier fits too.
The standard tier fits (106.2 of 192 GB). The best tier fits too.
The standard tier fits with changes: Hosted-default video (MiniMax H3 Max) is a call to fal; LTX-2.5 self-host video runs on the Mac, about 3x slower than a Blackwell card
The standard tier fits with changes: Hosted-default video (MiniMax H3 Max) is a call to fal; LTX-2.5 self-host video runs on the Mac, about 3x slower than a Blackwell card
Memory per component comes from measured footprints, the tool's stack.json, or an estimate from its parameter count, and each is labelled that way below. Only an RTX PRO 6000 and an M3 Ultra Mac Studio have actually been run.
On request. The container images and the compose file aren’t public yet. Ask for self-host access and Decosa sends the registry (DECOSA_REGISTRY) and the compose file’s URL (DECOSA_COMPOSE_URL) these steps use. They are the steps we tested end to end on a fresh machine.
The driver must see the GPU, and Docker must be able to pass it into a container.
nvidia-smi
docker compose version
docker run --rm --gpus all ubuntu nvidia-smi
One file describes the API and the language model as services.
mkdir -p ~/decosa && cd ~/decosa
curl -fsSL "${DECOSA_COMPOSE_URL}" -o compose.yamlThe first start downloads pinned model weights, tens of gigabytes.
docker compose pull
docker compose up -d
Wait until the API reports ok with the language model loaded. Then point your app at the local base URL.
curl -fsS http://localhost:<PORT>/healthz
# {"ok": true, "llm": true, ...}
curl -fsS -X POST http://localhost:<PORT>/demo/session \
-H 'Content-Type: application/json' -d '{"vertical":"studio"}'expected.json. Every check must print PASS.docker compose exec api python scripts/rehearse.py studio
Download the mock-data bundle (942 KB, 11 checks)expected.json
One finished studio render (a 5 s Wan2.1 video from the gallery), a copy with one byte changed, and a music prompt that imitates a named artist. The gallery must list music, images and video; the render must check as credentialed with a valid render receipt; the changed copy must check as tampered; and the imitation prompt must be refused (HTTP 422) before any job exists. No new render: renders take the shared GPU for minutes and hosted video is paid.
Licence: rainy-window-credentialed.mp4: rendered by Decosa with Wan-AI/Wan2.1-T2V-14B (Apache-2.0) from an original prompt; no real people. CC0 for the clip; the copy with one changed byte is the same clip.
# Decosa Studio: run it yourself (containers)

You are setting up Decosa Studio to run entirely on this machine's NVIDIA GPU(s). Nothing is sent to Decosa's
hosted API and there are no Decosa charges. The local service speaks the same API as the hosted one, so apps built
against the hosted API only need a new base URL.

Status: the container images (${DECOSA_REGISTRY}/decosa-*) and the compose file are on request while self-host is in early access (not on a public registry yet): ask at https://decosa.ai/contact?topic=self-host, and Decosa sends the registry as DECOSA_REGISTRY, the compose file URL as DECOSA_COMPOSE_URL, and pull access. If a pull fails with
"not found", "denied" or "unauthorized", stop and tell me. Do not substitute other images.

Hardware: 1x RTX PRO 6000 (96 GB). Two RTX 5090s are not enough for the studio models. Linux x86_64 with a recent NVIDIA driver.

Ask me before any command that needs sudo, and show me the command first.

## Step 0: set up with a coding agent, rehearse on mock data, then go private

This prompt is for a coding agent running on the machine that will host the service. We recommend Claude Code with
Claude Opus 5.5; any capable coding agent works. Work in this order:

1. Set up on mock data only. During the whole setup you (the agent) work with the synthetic sample bundle below and
   nothing else. Do not ask me for real data, and do not open, read, list or copy files that hold real data, even to
   "test with something realistic".
2. Rehearse. When the steps below are done and the service is healthy, fetch the mock-data bundle for this tool,
   https://decosa.ai/samples/studio.zip (942 KB, 11 checks, synthetic or openly licensed: see `licence` in expected.json),
   show me what is in it, and run the rehearsal against the local API:
   `docker compose exec api python scripts/rehearse.py studio` (the api image carries the same bundle under /app/rehearsal/studio/;
   with no key set, the script asks the local API for a short demo token). From a decosa-api checkout instead:
   `python scripts/rehearse.py studio --bundle studio.zip --base-url http://127.0.0.1:<PORT>`.
   It sends the mock inputs to the local API and prints PASS or FAIL for each expected property (for example: "the gallery lists music, images and video", "the gallery has at least one video", "every MiniMax-Music3 track carries its licence notice"). Show me
   the full output. Every check must pass. If one fails, fix the install and run it again; never edit `expected.json`
   to make a check pass.
3. Stop there. Once the rehearsal passes, tell me, and I will run my own data against the local API myself, on this
   machine.

For the person running this: a coding agent that runs in the cloud sees everything in its context, including files it
reads, command output and anything pasted into the chat. Keep real data out of the chat and out of anything the agent
can read. Switch to your own data only after the rehearsal has passed and the agent's work is done.

## Steps
1. Check the GPU and driver: `nvidia-smi`. If it fails, stop and tell me; do not install drivers without asking.
   Check free disk: the first start downloads model weights (tens of GB).
2. Docker: if `docker compose version` fails, install Docker Engine and the compose plugin using Docker's official
   instructions for this distribution (docs.docker.com/engine/install). Add me to the `docker` group only if I agree.
3. NVIDIA Container Toolkit: if `docker run --rm --gpus all ubuntu nvidia-smi` fails, install the toolkit using
   NVIDIA's official instructions (docs.nvidia.com/datacenter/cloud-native/container-toolkit/latest/install-guide.html),
   then run `sudo nvidia-ctk runtime configure --runtime=docker` and `sudo systemctl restart docker`. Re-run the check.
4. Fetch the compose file:
   `mkdir -p ~/decosa && cd ~/decosa && curl -fsSL "${DECOSA_COMPOSE_URL}" -o compose.yaml`
   Read it. If it references an `.env` file or variables, ask me for any values. Never print secrets.
5. Pull and start: `docker compose pull && docker compose up -d`.
6. Wait for health. Find the host port that compose.yaml publishes for the API (`docker compose ps`), then poll
   `curl -fsS http://localhost:<PORT>/healthz` every 10 s until it answers (`asr` and `llm` may be false: the studio
   uses neither, except the optional model check on prompts). The first start can take a while as weights download. Show me `docker compose logs --tail=50` if it
   has not come up after 20 minutes.
7. Smoke test: `curl -fsS -X POST http://localhost:<PORT>/demo/session -H 'Content-Type: application/json' -d '{"vertical":"studio"}'`
   should return a token. Queue one short music job with it (`POST /studio/jobs`, see the hosted prompt) and poll
   `GET /studio/jobs/{id}` until `done`; about 40 s for MiniMax-Music3 once the model is loaded.
8. Report back: GPU model(s) and memory, Docker and toolkit versions, the `/healthz` output, and the local base URL.

No NVIDIA GPU? Parts of this tool also run on an Apple Silicon Mac (MLX, 64 GB of unified memory or more): use https://decosa.ai/prompts/studio-mac.md instead.
Pick your GPU or Mac, or enter its memory. You get the tier that fits, the model swaps it needs, measured speed where we have it, and a setup prompt with those choices written in.
GeForce RTX 5090: 32 GB GDDR7, 1,792 GB/s, FP8 and NVFP4. NVIDIA product page
Doesn't fitDecosa Studio on GeForce RTX 5090
Needs about 50 GB of GPU memory at the smallest settings; 32 GB available.
Not measured.
Not measured on this hardware. The only measured setups are an RTX PRO 6000 Blackwell and a Mac Studio M3 Ultra.
The self-host prompt for Decosa Studio, with a hardware plan for GeForce RTX 5090 added after Step 0. Loading the full prompt; until then it points your agent at the prompt's URL.
# Set up Decosa Studio on my hardware

Fetch https://decosa.ai/prompts/studio-selfhost.md and follow it (including Step 0: rehearse on mock data first), with the hardware plan below applied.

## Hardware plan for this machine (from https://decosa.ai/self-host/hardware?use=studio)

Target machine: GeForce RTX 5090 (32 GB of GPU memory; CUDA, FP8 and NVFP4).
Quality tier: Lite · drafts on one 24–32 GB card (lite). Fit check: doesn't fit; some memory numbers are estimates, not measurements.

First, check the machine: run `nvidia-smi` (or `rocm-smi`, or `sysctl hw.memsize` on a Mac) and confirm the GPUs and free memory match the line above. If they do not, stop and tell me before pulling anything.

Use these components (the setup below describes the standard tier; change it to match):
- Music generation, fast drafts: ACE-Step 1.5 turbo + 5Hz LM 1.7B (ACE-Step/Ace-Step1.5), 14.6 GB
- Image generation, fast drafts: Z-Image-Turbo (Tongyi-MAI/Z-Image-Turbo), unknown
- Video generation, drafts: Wan2.1-T2V-1.3B (Wan-AI/Wan2.1-T2V-1.3B), 7.2 GB
- Text to speech: Kokoro-82M (hexgrad/Kokoro-82M), 1.4 GB
- Video generation: Wan2.1-T2V-14B (Wan-AI/Wan2.1-T2V-14B), 68.2 GB

Memory is not known for: Z-Image-Turbo (memory not known). Load them one at a time and watch memory before running everything together.

Warning: the fit check says this tier does not fit: Needs about 69.6 GB of GPU memory at the smallest settings; 32 GB available. Tell me before going further.

During the rehearsal, watch GPU memory. If a model fails to load or runs out of memory, lower its --max-model-len and --max-num-seqs first, then its memory share, and tell me what you changed.

The stack's own component list and compose layout: https://decosa.ai/prompts/studio-assemble.md
Some parts run natively on Apple Silicon (64 GB or more); the rest needs a CUDA GPU or a hosted API. Measured speeds and what runs where
From a checkout of decosa-api, one command sets up the models and the API: scripts/mac/setup.sh
# Decosa Studio: run it on this Mac (Apple Silicon, no NVIDIA GPU)

You are setting up the Decosa Studio on this Mac, natively on Apple Silicon. The models run on the Mac's GPU
through MLX and decosa-api runs from a git checkout with `uv`. Docker is not used for the models, because Docker on
macOS cannot reach the GPU. Nothing is sent to Decosa's hosted API.

Only part of this tool runs on a Mac (see the gaps below). The parts that do need 64 GB of unified memory or more.

Ask me before any command that needs sudo or installs software with Homebrew, and show me the command first. Never stop
or kill a process this setup did not start; if a port is taken, pick another one.

## Step 0: set up with a coding agent, rehearse on mock data, then go private

This prompt is for a coding agent running on the machine that will host the service. We recommend Claude Code with
Claude Opus 5.5; any capable coding agent works. Work in this order:

1. Set up on mock data only. During the whole setup you (the agent) work with the synthetic sample bundle below and
   nothing else. Do not ask me for real data, and do not open, read, list or copy files that hold real data, even to
   "test with something realistic".
2. Rehearse. When the steps below are done and the service is healthy, fetch the mock-data bundle for this tool,
   https://decosa.ai/samples/studio.zip (942 KB, 11 checks, synthetic or openly licensed: see `licence` in expected.json),
   show me what is in it, and run the rehearsal against the local API:
   `.venv/bin/python scripts/rehearse.py studio` in the decosa-api checkout (the key comes from ~/.decosa-mac/api.key).
   It sends the mock inputs to the local API and prints PASS or FAIL for each expected property (for example: "the gallery lists music, images and video", "the gallery has at least one video", "every MiniMax-Music3 track carries its licence notice"). Show me
   the full output. Every check must pass. If one fails, fix the install and run it again; never edit `expected.json`
   to make a check pass.
3. Stop there. Once the rehearsal passes, tell me, and I will run my own data against the local API myself, on this
   machine.

For the person running this: a coding agent that runs in the cloud sees everything in its context, including files it
reads, command output and anything pasted into the chat. Keep real data out of the chat and out of anything the agent
can read. Switch to your own data only after the rehearsal has passed and the agent's work is done.

## What runs where

| Part | On an NVIDIA GPU | On this Mac | Status |
|---|---|---|---|
| Music generation (songs with vocals and lyrics) | ComfyUI on CUDA | Community MLX port (PocketAiHub/MiniMax-Music3-MLX, INT8) | Runs, measured |
| Image generation | diffusers on CUDA | mflux 0.20 (mlx-community/Qwen-Image-2512-4bit, 26 GB) | Untested on a Mac |
| Hosted video (default): 5 s clips with audio | fal's hosted API | The same hosted API, called from the Mac | Hosted API |
| Text to speech (preset voices) | kokoro package on CPU | kokoro package on CPU | Runs, not measured |
| Voice cloning (consent-gated) | PyTorch on CUDA | PyTorch on MPS | Untested on a Mac |

Not on a Mac:
- Hosted-default video (MiniMax H3 Max) is a call to fal; LTX-2.5 self-host video runs on the Mac, about 3x slower than a Blackwell card.
- Qwen-Image through mflux and IndexTTS are untested.

## Steps
1. Check the machine: `uname -m` must print `arm64` (an M-series chip; Intel Macs cannot run MLX), and
   `sysctl -n hw.memsize` should be at least 64 GB for this tool. Check about 30 GB of free disk with
   `df -h ~`. Show me the chip (`sysctl -n machdep.cpu.brand_string`) and the memory.
2. Tools: `uv --version`. If it is missing, ask me, then `brew install uv`.
3. Code: `git clone <decosa-api source: on request at https://decosa.ai/contact?topic=self-host> ~/decosa-api` (access required) and `cd ~/decosa-api`.
   Check that `scripts/mac/setup.sh` exists; if it does not, the checkout is too old: stop and tell me.
4. Start everything with one command: `scripts/mac/setup.sh`. It creates `.venv` (decosa-api)
   and `.venv-mac` (MLX, mlx-lm, mlx-audio), downloads the weights with the Hugging Face CLI (about 16 GB for the
   language model), starts the model servers and decosa-api on 127.0.0.1, and mints a local API key
   into `~/.decosa-mac/api.key` (mode 0600). The first run takes a while because of the downloads; later runs reuse them.
   If a download fails with 401 or 403, ask me for a Hugging Face token and set `HF_TOKEN`.
   The script sets up only the language model. The parts listed under "Not on a Mac" still need
   the GPU stack or the hosted API (see https://decosa.ai/prompts/studio-assemble.md); the smoke test in step 6 will
   report them as failures. Tell me which checks passed and which need the GPU.
5. Check health: `scripts/mac/setup.sh status` shows each server, and `curl -fsS http://127.0.0.1:8445/healthz` must
   report `"llm": true`. `curl -fsS http://127.0.0.1:8445/attest/signing-key` shows this Mac's public key:
   show it to me, because it is what others pin to check the receipts and records this Mac signs.
6. Smoke test: `.venv/bin/python scripts/mac/bench_usecases.py studio`. It runs the tool's own sample end to end
   against the local API with the local key and prints `ok`, the wall time, the model calls and the receipts.
   `ok=True` is the pass condition. If it fails, read `~/.decosa-mac/logs/*.log` and tell me what you found.
7. Point the app at it: the API is `http://127.0.0.1:8445` with `Authorization: Bearer $(cat ~/.decosa-mac/api.key)`,
   the same routes as the hosted API. To stop everything: `scripts/mac/setup.sh stop`.
8. Report back: the chip and memory, the public key, the smoke-test result and its time, and the output of
   `scripts/mac/setup.sh status`.

## Good to know
- Receipts: every model call is signed with this Mac's own Ed25519 key and names the exact MLX weights
  (`qwen3.8-27b-mlx-4bit` with a hash of the downloaded files). There is no gateway countersignature on a
  self-hosted Mac.
- The weights are a 4-bit MLX build of the same open models, not the NVFP4 build the hosted route and the published
  evals use. Expect small differences in wording and scores.
- Faster drafting: `scripts/mac/setup.sh stop && scripts/mac/setup.sh --engine omlx` serves the
  model with oMLX and multi-token prediction (about 2x faster for a single long answer, no faster for many parallel
  calls; typed judgments then use sampling because oMLX returns no log-probabilities).
- Music (Music3 MLX port), images (Z-Image-Turbo through mflux, 32 s) and LTX-2.5 video with audio (MLX int8, 184 s per 5 s clip) were measured on the Mac.
- Measured speeds for a Mac Studio M3 Ultra and the memory each tool needs: https://decosa.ai/mac. Full details:
  `docs/self-host-mac.md` in the checkout.
Hosted: partial on 25 Sep 2026 · QA sweep · 1 receipt
Loading the nightly status…
Self-host: verified 25 Sep 2026 · Fresh clone of decosa-api; the api image plus ffmpeg running the repo's own studio worker against an already-running ComfyUI on the same box (no render or ComfyUI containers built, no new model loads).
Measured cost to run: about $0.029 per image (hosted, 25 Sep 2026). Self-hosting is free: the code is open and the models are open-weight. You pay only for your own hardware and power.
Verified on 2026-09-25: the image builds, the service starts, and the prompt's MiniMax-Music3 smoke job (seed 5501) finished in 40 s against a local ComfyUI equivalent to the documented one; model-server startup and the image and video paths were not re-verified. Two runs of the same seed gave bit-identical decoded PCM. An api restart mid-render marked that job failed with a reason and ran the queued one (72 s). Fixed on the way: the api image left out services/ (every render failed), jobs were lost on restart.
A render queue for songs, images and short videos, running open-weight models that load onto one GPU one at a time. Private checkpoints and LoRAs stay on your disk. Voice with consent-gated cloning is planned. It is built for creative teams and indie studios that want predictable costs and control over their weights.
A prompt, lyrics or reference image enters the decosa-api job queue. A local render worker swaps one open-weight model onto the GPU at a time: MiniMax-Music3 for songs (MiniMax-Music3 community licence, shown in the UI) with ACE-Step 1.5 as the Lite option (MIT), Qwen-Image-2512 for images (Apache-2.0) and Wan2.1-T2V-14B for video (Apache-2.0). LTX-2.5 and MiniMax-H3 appear only as self-host options because of their licences. Voice with a consent gate is planned. Finished files go to the gallery and the job status. For verification, each render would commit its seed, prompt hash and weights root in a signed receipt; a validator re-renders a sample of denoising steps and compares them within a tolerance, the gateway countersigns. This check is partial and not yet implemented. When self-hosted, the models, private checkpoints and voice samples stay local.
Same app at every tier. What changes is the models, the hardware they need, and whether receipts are signed. Scores are measured with the source named, or marked not measured.
drafts on one 24–32 GB card
Fast music drafts, draft images and small draft video on one consumer card. Quality is below the standard tier, and Z-Image-Turbo and Wan 1.3B are not tested yet.
the hosted demo, about 50 GB of one 96 GB card
The hosted gallery and queue: MiniMax-Music3 songs, Qwen-Image-2512 images and Wan2.1-T2V-14B video (silent), with ACE-Step clips as well. Every model's licence allows hosted use. Hosted video runs on MiniMax H3 Max through fal at list price with no markup (API key, 2 per key per day, daily cap); Wan2.1 stays the fully open option.
self-host only, a whole 96 GB card
Adds video with sound: MiniMax-H3 (licence pending; self-host available where its current licence covers you) or LTX-2.5 (below USD 10M revenue, not in a competing hosted service). Not in the hosted demo until the H3 licence lands.
MiniMax H3 on two cards, no offload
The studio's best video model, faster. Both halves of MiniMax-H3 in BF16 on two 96 GB cards, so nothing is offloaded to RAM: faster renders (estimate, not measured). Self-host now where H3's current licence covers you; once the pending licence lands we add this compute for the hosted tier ourselves. Not a community-provider model.
| Model | Tiers | Params · VRAM | Verification | Details |
|---|---|---|---|---|
Music generation, fast drafts (text and lyrics to song)ACE-Step 1.5 turbo + 5Hz LM 1.7BACE-Step/Ace-Step1.5 on Hugging Face (opens in a new tab) 2.39B DiT + 1.85B LM · 14.6 GBProof: partialIn the hosted demo | LiteStandard | 2.39B DiT + 1.85B LM · 14.6 GB | Proof: partialIn the hosted demo | |
| ||||
Music generation (songs with vocals and lyrics)MiniMax-Music3MiniMaxAI/MiniMax-Music3 on Hugging Face (opens in a new tab) 8.58B LM + 2.43B flow transformerProof: partialIn the hosted demo | StandardBest | 8.58B LM + 2.43B flow transformer | Proof: partialIn the hosted demo | |
| ||||
Image generation, fast draftsZ-Image-TurboTongyi-MAI/Z-Image-Turbo on Hugging Face (opens in a new tab) Proof: partialSelf-host only | Lite | n/a | Proof: partialSelf-host only | |
| ||||
20.4B (transformer) · 41.6 GBProof: partialIn the hosted demo | StandardBest | 20.4B (transformer) · 41.6 GB | Proof: partialIn the hosted demo | |
| ||||
1.3BProof: partialSelf-host only | Lite | 1.3B | Proof: partialSelf-host only | |
| ||||
Hosted video (default): 5 s clips with audioMiniMax H3 Max (via fal) No proof yetIn the hosted demo | Standard | n/a | No proof yetIn the hosted demo | |
| ||||
Video generation (text to video, no audio)Wan2.1-T2V-14BWan-AI/Wan2.1-T2V-14B on Hugging Face (opens in a new tab) 14BProof: partialSelf-host only | Lite | 14B | Proof: partialSelf-host only | |
| ||||
Video with synchronized audio, self-host onlyLTX-2.5 22B distilledLightricks/LTX-2.5 on Hugging Face (opens in a new tab) 21.0B (transformer)Proof: partialSelf-host only | Best | 21.0B (transformer) | Proof: partialSelf-host only | |
| ||||
Video with synchronized audio and reference control, self-host only where licensedMiniMax-H3 (licence pending)MiniMaxAI/MiniMax-H3 on Hugging Face (opens in a new tab) 33.1B (transformer) + 33.4B (text encoder) · about 133 GB (estimate)Proof: partialSelf-host only | BestWanted | 33.1B (transformer) + 33.4B (text encoder) · about 133 GB (estimate) | Proof: partialSelf-host only | |
| ||||
82MNo proof yetSelf-host only | Lite | 82M | No proof yetSelf-host only | |
| ||||
Voice cloning (consent-gated)IndexTTS-2.5IndexTeam/IndexTTS-2.5 on Hugging Face (opens in a new tab) No proof yetSelf-host only | n/a | n/a | No proof yetSelf-host only | |
| ||||
Runs the MiniMax-Music3 and Wan2.1 graphs (and LTX-2.5 for self-host); it is started only while a job needs it.
Qwen-Image-2512 in the render worker (and MiniMax-H3 for self-host where licensed).
Encodes WAV to MP3 and moves the MP4 index to the front for streaming.
${DECOSA_REGISTRY}/decosa-api:0.1.0Studio gallery (GET /studio/gallery), job queue (POST /studio/jobs, GET /studio/jobs/{id}) and static media under /studio/media; runs render jobs through DECOSA_STUDIO_WORKER=command.
Local GPU render worker, built from source: loads one model at a time, renders, writes the file to a shared volume and returns its path.
MiniMax-Music3 and Wan2.1 graphs, reached only by the render worker; models are unloaded through POST /free after each job.
Measured 2026-09-23: the gallery's music, images and video rendered on GPU0 with 45–48 GB already in use by other services.
Self-host best tier. MiniMax-H3 has run one job per card with about 115 GB offloaded to system RAM (measured before the licence review).
Not tested. ACE-Step (14.6 GB peak), Kokoro, Z-Image-Turbo and Wan2.1-1.3B are the realistic set; Qwen-Image-2512 peaked at 41.6 GB even with CPU offload.
Measuredmeasured on our server 2026-09-23: ACE-Step 1.5 turbo, 30 s clip, 8 steps, mean of 4 renders (3.5–4.3 s), after a 16 s model load
Measuredmeasured on our server 2026-09-23: MiniMax-Music3 in ComfyUI, 45 s max duration, 30 steps, prompt execution including model load, 3 renders (43.0, 64.8, 72.6 s) on about 50 GB of free VRAM
Measuredmeasured on our server 2026-09-23: Qwen-Image-2512, 50 steps, 1328×1328 or 1664×928, model CPU offload, median of 6 renders (92–104 s)
Measuredmeasured on our server 2026-09-23: Wan2.1-T2V-14B in ComfyUI, 832×480, 81 frames (5 s at 16 fps), 50 steps, 2 renders (35:26, 34:38; 41–46 s per step) on GPU0 shared with live services
Measuredmeasured on our server 2026-09-23: LTX-2.5 distilled INT8 in ComfyUI, 5 s 1280×704 with audio, 2 renders
Measuredmeasured on our server: MiniMax-H3 t2v 960×544, 124 frames, median of 36 renders, render-studio job records to 2026-09-03 (before the licence review)
Paste into Claude Code / Codex to assemble this stack locally. The prompt checks your GPU, pulls the pinned models, writes the compose file and runs a smoke test.
# Assemble Decosa Studio on this machine

You are setting up a local creative studio on ONE NVIDIA GPU: songs (MiniMax-Music3, with ACE-Step 1.5 as a fast option), images (Qwen-Image-2512) and video (Wan2.1-T2V-14B), plus the `decosa-api` queue and gallery. Only one model is on the GPU at a time. Work step by step, show me each command before you run anything with `sudo`, and stop to ask if a check fails.

## Step 0: set up with a coding agent, rehearse on mock data, then go private

This prompt is for a coding agent running on the machine that will host the service. We recommend Claude Code with
Claude Opus 5.5; any capable coding agent works. Work in this order:

1. Set up on mock data only. During the whole setup you (the agent) work with the synthetic sample bundle below and
   nothing else. Do not ask me for real data, and do not open, read, list or copy files that hold real data, even to
   "test with something realistic".
2. Rehearse. When the steps below are done and the service is healthy, fetch the mock-data bundle for this tool,
   https://decosa.ai/samples/studio.zip (942 KB, 11 checks, synthetic or openly licensed: see `licence` in expected.json),
   show me what is in it, and run the rehearsal against the local API:
   `docker compose exec api python scripts/rehearse.py studio` (the api image carries the same bundle under /app/rehearsal/studio/;
   with no key set, the script asks the local API for a short demo token). From a decosa-api checkout instead:
   `python scripts/rehearse.py studio --bundle studio.zip --base-url http://127.0.0.1:<PORT>`.
   It sends the mock inputs to the local API and prints PASS or FAIL for each expected property (for example: "the gallery lists music, images and video", "the gallery has at least one video", "every MiniMax-Music3 track carries its licence notice"). Show me
   the full output. Every check must pass. If one fails, fix the install and run it again; never edit `expected.json`
   to make a check pass.
3. Stop there. Once the rehearsal passes, tell me, and I will run my own data against the local API myself, on this
   machine.

For the person running this: a coding agent that runs in the cloud sees everything in its context, including files it
reads, command output and anything pasted into the chat. Keep real data out of the chat and out of anything the agent
can read. Switch to your own data only after the rehearsal has passed and the agent's work is done.

## 0. Ground rules and licences
- Default models, all usable self-hosted or hosted: MiniMax-Music3 (MiniMax-Music3 Community License), ACE-Step 1.5 (MIT), Qwen-Image-2512 (Apache-2.0) and Wan2.1-T2V-14B (Apache-2.0).
- MiniMax-Music3 duties: show "MiniMax-Music3" prominently in any commercial UI that plays its output. Keep abuse and IP-infringement safeguards on any hosted service, follow the Acceptable Use Policy (Exhibit A), and get written authorization from MiniMax above USD 20M yearly revenue.
- Optional video with sound (self-host only, never for a hosted service you offer to others):
  - LTX-2.5 (LTX-2 Community License): free only below USD 10M annual revenue. Pass the licence and Attachment A on to anyone you distribute to. Item 20 bars use in a product that competes directly with the licensor's without a commercial licence.
  - MiniMax-H3 (MiniMax H3 Community License): not licensed in the US, EU, UK or South Korea. Before you download any H3 weights, **ask me to confirm** that my jurisdiction is covered, or that I hold a licence from MiniMax (api@minimax.io). If I don't confirm, skip H3 (and the H3-Turbo LoRA) and stay on Wan2.1. If you do use H3, show "Powered by MiniMax H3" and give users terms that carry its use restrictions.
- Do NOT substitute Qwen-Image-2.1 (research-only licence) or OmniVoice (non-commercial weights). Never render a real person's likeness or clone a real voice.
- Nothing leaves this machine. Bind every port to 127.0.0.1.

## 1. Check the GPU, driver and Docker
1. Run `nvidia-smi`. You need at least 48 GB of free VRAM and 64 GB or more of system RAM. Measured on an RTX PRO 6000 with about 50 GB free: ACE-Step peaked at 14.6 GB, Qwen-Image-2512 at 41.6 GB with CPU offload, and Music3 and Wan 14B both ran. Blackwell cards (sm_120) need a driver with CUDA 13.0 support.
2. If `docker` is missing, install Docker Engine (docs.docker.com). If `docker run --rm --gpus all ubuntu nvidia-smi` fails, install the NVIDIA Container Toolkit (nvidia.github.io/libnvidia-container), then run `sudo nvidia-ctk runtime configure --runtime=docker && sudo systemctl restart docker`.
3. Check disk space: the default models need about 170 GB.

## 2. Pull the models (pinned revisions)
Create `~/decosa-studio/{models,renders,worker,render,comfyui}`, run `pip install -U huggingface_hub`, then:
- `hf download Comfy-Org/MiniMax-Music-3 --revision 6baad88896848433857c170ba4f05d2ea9d5f218 --local-dir models/music3 --include "diffusion_models/minimax_music3_dit_fp16.safetensors" "text_encoders/minimax_music3_text_encoder_pruned_bf16.safetensors" "vae/minimax_music3_dav.safetensors"`. This is a repackage of MiniMaxAI/MiniMax-Music3. It is tagged Apache-2.0, but the upstream MiniMax-Music3 licence governs.
- `hf download ACE-Step/Ace-Step1.5 --revision 19671f406d603126926c1b7e2adc169acbcade22 --local-dir models/ace-step`
- `hf download Qwen/Qwen-Image-2512 --revision 25468b98e3276ca6700de15c6628e51b7de54a26 --local-dir models/qwen-image-2512`
- `hf download Wan-AI/Wan2.1-T2V-14B --revision a064a6c71f5be440641209c07bf2a5ce7a2ff5e4 --local-dir models/wan2.1-t2v-14b`. Check each safetensors file's size and SHA-256 against the Hugging Face listing. ComfyUI's `UNETLoader` wants a single file, so merge the six shards unchanged with `safetensors` (load each shard, `save_file` the combined dict to `wan2.1_t2v_14B_fp32_merged.safetensors`). Also convert the encoder: `models_t5_umt5-xxl-enc-bf16.pth` is not in ComfyUI's format, so use `split_files/text_encoders/umt5_xxl_fp16.safetensors` from `Comfy-Org/Wan_2.1_ComfyUI_repackaged` (Apache-2.0, revision 123acf1cc74bccbb9bfff8ac1ee72edc08c2341d) and keep `Wan2.1_VAE.pth` as the VAE.

## 3. Images
- `${DECOSA_REGISTRY}/decosa-api:0.1.0` (**publishing soon**). If the pull fails, build from source: `git clone <decosa-api source: on request at https://decosa.ai/contact?topic=self-host>` (access required), then `docker build -f docker/api/Dockerfile -t ${DECOSA_REGISTRY}/decosa-api:0.1.0 .`.
- Build two images locally, since no render image is published:
  - `decosa-render:local`: `python:3.12-slim` plus `ffmpeg` and `git`; `torch==2.13.0` from `https://download.pytorch.org/whl/cu130`; `diffusers` from `git+https://github.com/huggingface/diffusers@abc5e9bf71fd38f53cd471bc3acaa84bc5ecbfdc`, plus `transformers`, `accelerate`, `fastapi` and `uvicorn`; and ACE-Step (tested in its own venv on torch 2.10.0+cu128; Qwen-Image was tested on torch 2.13.0+cu130, so if the two conflict, give ACE-Step its own venv) installed with `git clone https://github.com/ace-step/ACE-Step-1.5 /opt/acestep && git -C /opt/acestep checkout 75fcfbddd5662f790defac0cb1bc27525142a7cf && pip install -e /opt/acestep`.
  - `decosa-comfyui:local`: torch 2.11.0 (cu128 was the tested build; use cu130 on Blackwell if cu128 fails), plus `git clone https://github.com/comfyanonymous/ComfyUI /opt/ComfyUI && git -C /opt/ComfyUI checkout 30bdda1ef13a3a34fce2cd2fec633f15d832122a && pip install -r /opt/ComfyUI/requirements.txt`. Add an `extra_model_paths.yaml` that maps the Music3 and Wan files into `diffusion_models`, `text_encoders` and `vae`.

## 4. The render worker (`render/app.py`, FastAPI on port 8460)
Reference implementation: decosa-api ships the same recipes in `scripts/studio_worker.py` (music, video, ACE-Step) and
`services/studio/` (`workflows/music3.api.json`, `workflows/wan21-t2v-14b.api.json`, `qwen_image.py`,
`acestep_render.py`). Read them first and reuse the two ComfyUI workflow files as they are, rather than writing the graphs
by hand. The shipped worker also works on its own: inside an api image that has `ffmpeg`, set
`DECOSA_STUDIO_WORKER_CMD=python /app/scripts/studio_worker.py` and `DECOSA_STUDIO_COMFY_URL=http://comfyui:8188`, and
music and video run through ComfyUI with no render service. Images still need the diffusers environment below.
- `POST /render` takes `{job_id, kind, prompt, params}`. One global lock runs one job at a time.
- **Sequential swap:** keep at most one model resident. Before switching, drop the diffusers pipeline (`del`, `gc.collect()`, `torch.cuda.empty_cache()`) or call ComfyUI `POST /free` with `{"unload_models":true,"free_memory":true}`. That call also clears ComfyUI's result cache, so a repeated job really re-renders.
- **Seed:** use `params.seed` if given, otherwise a random 31-bit integer. Write `/renders/<job_id>.json` with the seed, prompt, model id, revision and all sampler settings.
- **music** (default engine MiniMax-Music3; `params.engine="ace-step"` selects the fast model). Send ComfyUI this graph:
  - `UNETLoader(minimax_music3_dit_fp16)`, `CLIPLoader(minimax_music3_text_encoder_pruned_bf16, type "minimax")` and `VAELoader(minimax_music3_dav)`;
  - `MiniMaxMusic3TextEncode(caption, lyrics, seed, max_duration, cfg_scale=1.7, top_k=50)`, feeding a `ConditioningZeroOut` negative and `EmptyMiniMaxMusic3LatentAudio(seconds from the encoder)`;
  - `KSampler(seed, 30 steps, cfg 1.7, euler, simple)`, then `VAEDecodeAudio` and `SaveAudio`, then encode to MP3.
  - For ACE-Step, use `acestep.inference.generate_music` with `acestep-v15-turbo`, `acestep-5Hz-lm-1.7B` (backend `pt`), 8 steps and `infer_method="ode"`.
- **image:** load `QwenImagePipeline` in bf16 with `enable_model_cpu_offload()`. Use 50 steps, `true_cfg_scale=4.0`, `torch.Generator("cuda").manual_seed(seed)` and 1328×1328 by default.
- **video:** send ComfyUI this graph:
  - `UNETLoader(wan2.1_t2v_14B_fp32_merged)`, `CLIPLoader(umt5_xxl_fp16, type "wan")` and `VAELoader(Wan2.1_VAE.pth)`;
  - `CLIPTextEncode` for the prompt and the negative, then `ModelSamplingSD3(shift=5.0)`;
  - `EmptyHunyuanLatentVideo(832, 480, 81 frames)`, then `KSampler(seed, 50 steps, cfg 5.0, uni_pc, simple)`, `VAEDecode`, `CreateVideo(fps=16)` and `SaveVideo(mp4)`, then `ffmpeg -c copy -movflags +faststart`. Wan2.1 has no audio track.
- Write outputs with mode 0644 (the api runs as uid 10001). Return `{"file": "/renders/<job_id>.<ext>"}` or `{"error": "..."}`.
- `worker/submit.py`, mounted into the api container, reads the job JSON from stdin, POSTs it to `http://render:8460/render` with a 60-minute timeout, and prints the one JSON line it gets back.

## 5. `docker-compose.yml` (all ports on 127.0.0.1)
- `api`: `${DECOSA_REGISTRY}/decosa-api:0.1.0`, `127.0.0.1:8445:8445`, volumes `decosa-data:/data`, `./worker:/worker:ro` and `./renders:/renders:ro`. Environment: `DECOSA_STUDIO_WORKER=command`, `DECOSA_STUDIO_WORKER_CMD=python /worker/submit.py`, `DECOSA_STUDIO_VIDEO_BACKEND=wan` (local Wan2.1; the hosted service's
default is MiniMax H3 through fal, which needs a fal account), `DECOSA_CORS_ORIGIN_REGEX=^https?://(localhost|127\.0\.0\.1)(:\d+)?$`. Health check: `GET /healthz` (`asr` and `llm` may be false because studio does not use them).
- `render`: `decosa-render:local`, one GPU (`deploy.resources.reservations.devices`), `ipc: host`, `./models:/models:ro`, `./renders:/renders`, `127.0.0.1:8460:8460`. Health check: `GET /health` returns `{"ok":true,"loaded":<kind or null>}`.
- `comfyui`: `decosa-comfyui:local`, the same GPU, `./models:/models:ro`, command `python /opt/ComfyUI/main.py --listen 0.0.0.0 --port 8188 --reserve-vram 4 --disable-auto-launch`, with no host port. Health check: `GET /system_stats`.
- `api` depends on `render` being healthy; `render` depends on `comfyui` being healthy.

## 6. Smoke test
```bash
B=http://127.0.0.1:8445
T=$(curl -s -X POST $B/demo/session -H 'content-type: application/json' -d '{"vertical":"studio"}' | jq -r .token)
J=$(curl -s -X POST $B/studio/jobs -H "authorization: Bearer $T" -H 'content-type: application/json' \
  -d '{"kind":"music","prompt":"indie folk, fingerpicked acoustic guitar, warm and hopeful","params":{"seed":5501,"lyrics":"[verse]\nLights along the quay"}}' | jq -r .job_id)
until curl -s $B/studio/jobs/$J | jq -e '.status=="done" or .status=="failed"' >/dev/null; do sleep 3; done
curl -s $B/studio/jobs/$J    # expect {"status":"done","kind":"music","url":"/studio/media/jobs/<id>.mp3"}
```
Repeat with `"kind":"image"`, then `"kind":"video"` (expect minutes, not seconds, for Wan 14B). Each token allows at most 3 jobs.
Jobs survive an api restart: a queued job is queued again, and one that was running comes back `failed` with a reason
(the file `studio/jobs.json` in the data volume holds no tokens and no prompts of started jobs).

**Re-render check:** run the same music or image job twice with the same seed, and compare decoded PCM or pixels. On the reference machine, MiniMax-Music3 and Qwen-Image-2512 were bit-identical on the same GPU and software, and ACE-Step was not. Report what you measure and never claim a match you did not see.

**Gallery:** copy files into the `decosa-data` volume under `studio/media/gallery/` and list them in `studio/gallery.json` as `[{"id","kind","title","prompt","model","file":"gallery/<name>","seed","duration_s"}]`. For Music3 entries, include "Powered by MiniMax-Music3" in `model`. Do not put LTX-2.5 or MiniMax-H3 output in a gallery that others can reach.

## 7. Point the app at the local API
Set `NEXT_PUBLIC_DECOSA_API=http://127.0.0.1:8445` in the web app's `.env.local` and restart its dev server. Localhost origins are already allowed by CORS.

## 9. Troubleshooting
- **Out of memory on images:** keep CPU offload on, and drop to 1024×1024 before you cut steps.
- **Wan is very slow:** the full-precision 14B runs at about 40 s per step when memory is shared. Use 30 steps for drafts, or Wan2.1-T2V-1.3B.
- **403 on a download:** the model is gated, or `HF_TOKEN` is missing.
- **`no kernel image is available`:** torch is not a cu130 build.
- **Unknown node in ComfyUI:** the checkout is not at the pinned commit.
- **A job stays `queued` with a `note`:** `DECOSA_STUDIO_WORKER` is not `command`, or `submit.py` cannot reach `render`.
- **Gallery is empty:** a `file` in `gallery.json` does not exist under `studio/media/`.

Finish by printing a table: each service, its URL and health, the model revision on disk, and the measured time of each smoke job.Last reviewed
There is no quality eval yet, on any tier. The one check so far is reproducibility: a same-seed re-render was bit-identical for MiniMax-Music3 and Qwen-Image-2512, and not for ACE-Step. That shows reproducibility, not quality.
Yes. Decosa Studio's standard tier, the hosted demo, uses about 50 GB of one 96 GB RTX PRO 6000 Blackwell card, with models loading one at a time. The best tier, video with sound from LTX-2.5 or MiniMax-H3, needs the whole 96 GB card and self-hosting. A lite tier for one 24-32 GB card exists, but Z-Image-Turbo and Wan 1.3B are not tested yet.
Decosa Studio runs open-weight models: ACE-Step and MiniMax-Music3 for songs, Qwen-Image-2512 for images and Wan2.1-T2V-14B for video, with MiniMax H3 Max through fal as the hosted video default. LTX-2.5 and MiniMax-H3 are self-host only because of their licences. MiniMax-Music3 output must be credited 'Powered by MiniMax-Music3'. Voice cloning is planned and needs documented consent from the speaker.
Measured on 2026-09-25, Decosa Studio produced a song in about 40-70 seconds, an image in about 2 minutes and a 5 second Wan2.1 video clip in about 35 minutes on the shared GPU. Renders share that GPU with the live audio demos, so a job pauses while a live session runs. Output quality has not been measured on any tier yet.
When Decosa Studio is self-hosted, nothing leaves the box. On the hosted service, your prompt reaches Decosa's render service and a text-model prompt check through our gateway, and hosted video prompts go to fal at list price with no markup. Logs carry prompt hashes, never prompts, and private checkpoints and LoRAs stay on your disk.
Not yet. Decosa Studio has no quality eval on any tier. The one check so far is reproducibility: a same-seed re-render was bit-identical for MiniMax-Music3 and Qwen-Image-2512, and not identical for ACE-Step. That shows reproducibility, not quality. Each render does carry a C2PA credential and a signed render receipt, which is Decosa's statement of model, seed, weights and output hash; nobody re-renders to check it.
We read every message. Questions, comments and our answers show here once we have reviewed and approved them.
Loading questions…